
On Monday, a Claude Code user posted on X that his plan had lasted a full week before the last reset on Saturday. Two days into the new week, he was already at 65%. Another developer, whose team had scored Claude Fable 5.2 at 94/100 on a private benchmark (first of 53 models), wrote that his 20x weekly limit had reset the day before. After one day on Opus 5.5 and a second day mixing Fable 5.2 with Opus 5.5, he was down to 37%.
The easy reading is that limits shrank or the meter is broken. Some of that may be true, and we come back to it below. But the same complaint shows up after every frontier launch, and most of it traces back to a choice users control: running the newest, most expensive model on every turn of every session.
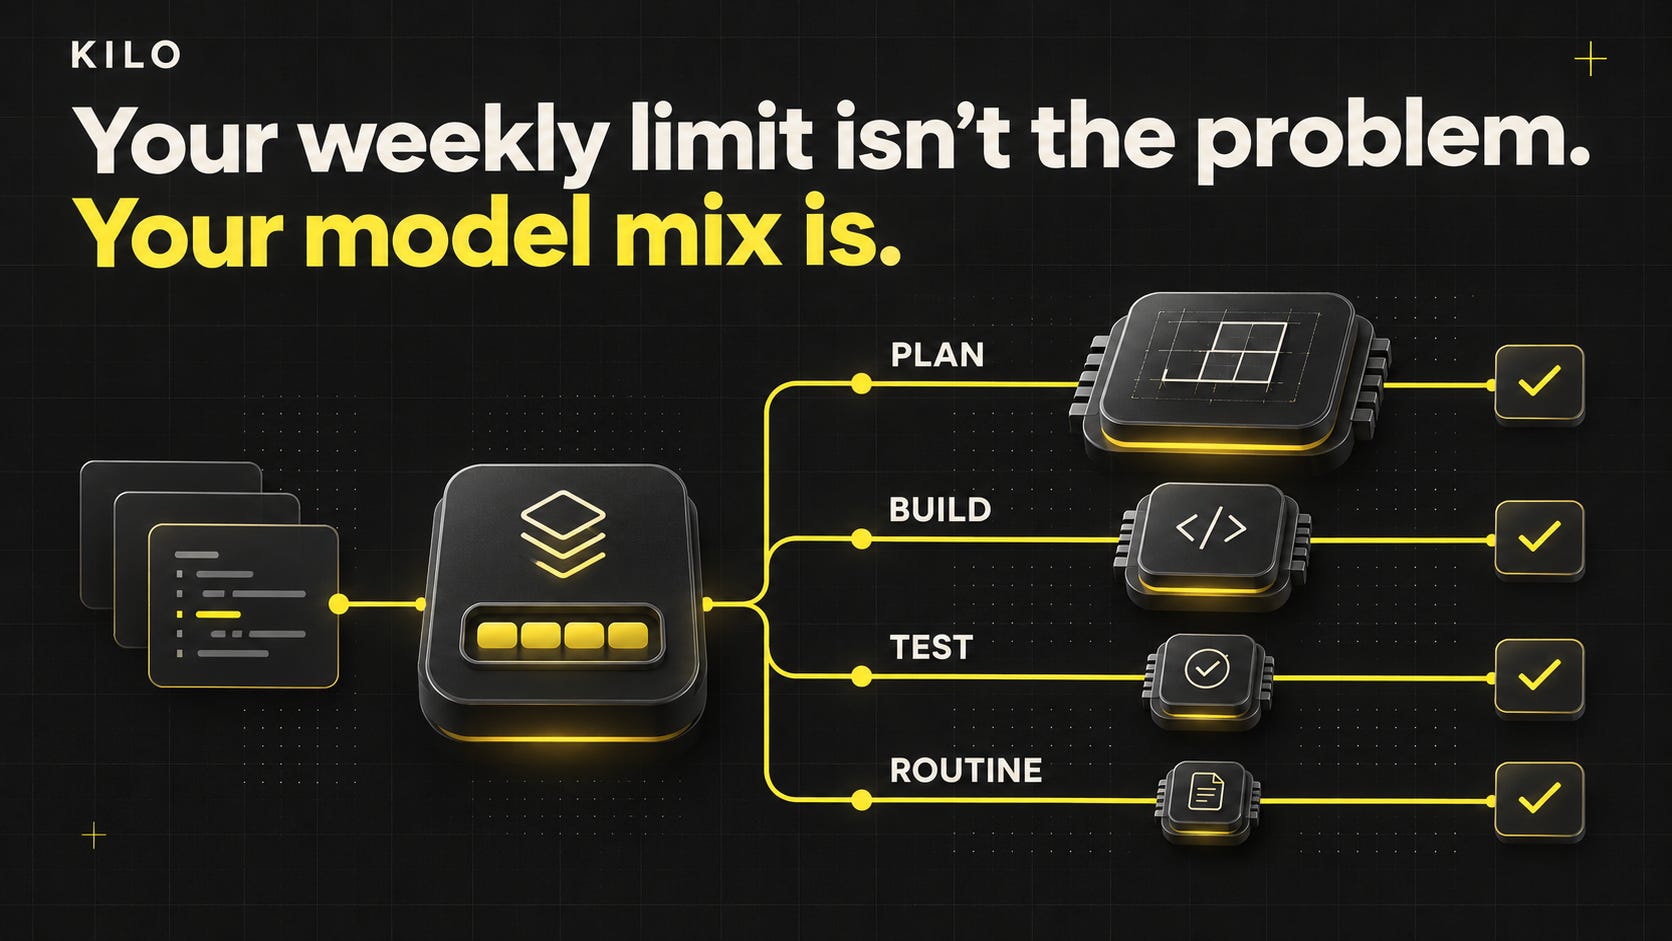
A weekly limit is a budget, and right after a launch most of us spend it as if we had a single-model subscription.
What changed on November 9
Anthropic released Fable 5.2 on November 9 at $8 per million input tokens and $40 per million output tokens, down 20% from Fable 5.1’s $10 and $50 (pricing breakdown). That is still twice the price of Opus 5.5 (4/20) and four times Sonnet 5.5 (2/10).
A solo founder in Bengaluru put it plainly: for him, the price drop matters more than the benchmarks. That’s a fair way to look at it, and the cut is real. Cheaper than 5.1 is still a long way from cheap, though. On a subscription, the number that matters is how fast each turn moves the meter, and Fable still moves it fastest.
On Max plans and premium Team seats, Fable counts toward your regular weekly limit, capped at 50% of it, and Anthropic’s own help page says it uses those limits faster than other Claude models.
Why the meter outruns the work
Three things stack up in a launch week.
Per-token weight. Every Fable turn costs roughly twice an Opus turn at list price. If your workflow didn’t change and your model did, your burn rate doubled.
Context is most of the bill. Agent sessions spend most of their tokens reading files, logs and tool output. When Fable does the reading, every grep result and test log is billed at the top rate.
Bugs happen. After earlier releases, users filed issues describing meters that drained several times faster than expected, and in at least one case Anthropic reset limits afterwards.
The first two are choices. A bug can explain a sudden spike. It can’t explain a week in which every turn ran on the most expensive model available.
The half of your limit Fable can’t touch
Theo Browne logs every request he makes in Claude Code so he can see what real work burns. On November 10 he pointed out the consequence of the 50% cap: if you use Fable exclusively, half of your weekly limit is effectively lost. He posted a chart of the gap.
[IMAGE: embed or screenshot Theo’s chart, captioned “Chart: Theo Browne (@theo) on X”]
This is the part most launch-week complaints miss. With a model-specific cap, your model mix sets your ceiling. A Fable-only week ends at half your plan, however much room the overall meter still shows. The other half only exists if you spend it on Opus, Sonnet or another model your plan covers. It works in the other direction too: Anthropic’s help page explains that if you’ve already used half your weekly limit on other models, Fable can only use what’s left.
So two developers on the same plan can have very different weeks. One runs Fable on everything, hits the Fable wall by Wednesday and leaves half the plan unused. The other saves Fable for the turns where its judgment pays off, lets cheaper models do the bulk of the typing, and finishes the week having used both halves.
What the mix does to cost
Anthropic doesn’t publish how many tokens each plan includes, so we can’t model the subscription meter directly. API list prices show the shape of the tradeoff. Take a session that reads 1M input tokens and writes 100K output tokens:
Fable 5.2: $8.00 input + $4.00 output = $12.00 per session
Opus 5.5: $4.00 input + $2.00 output = $6.00 per session
Sonnet 5.5: $2.00 input + $1.00 output = $3.00 per session
Now assume planning takes 20% of a feature’s tokens and implementation takes 80%. Running everything on Fable costs $12. Planning on Fable and implementing on Opus 5.5 costs $7.20, about 40% less. Planning on Fable and implementing on Sonnet 5.5 costs $4.80, about 60% less.
The caveat is the one that always applies: a cheaper model that needs three attempts is not cheaper. Cost per successful task is the number to watch, which is why the handoff below matters as much as the model choice. At All Day AI, Chris Clark of OpenRouter put numbers on it: open-weight models now carry about 64% of the tokens on his platform but only 28% of the spending, and the cheapest saving he sees is agents left pinned to an expensive model (full recap).
A mix that lasts the week
The rule we’d start from: put Fable where a wrong decision costs more than the tokens do. In practice that looks something like this.
Fable 5.2: planning, architecture, debugging that cheaper models have already stalled on, and review of risky diffs such as auth, migrations and concurrency.
Opus 5.5: most implementation work, starting from a written plan.
Sonnet 5.5: exploring the codebase, reading logs, writing tests from a clear spec and small edits.
Small or open-weight models: background chores like commit messages, session titles and summaries.
The handoff is what makes this work. When we compared Claude Fable 5 and GPT-5.5, we gave Fable’s plan to both models as a plan.md file in a fresh session with no other context. Fable won on planning, and execution came out similar. A good written plan carries most of the frontier model’s value into a cheaper implementation session, without dragging Fable’s whole context along.
Where Kilo fits
Everything above works with discipline alone. Kilo makes it the default instead of something you have to remember.
In Kilo you can set a default model per agent in the Models tab or in kilo.jsonc, so the plan agent can sit on Fable 5.2 while the code agent runs on Opus 5.5 or Sonnet 5.5. A session override is always one click away when a task needs more.
If you’d rather not maintain that mapping, Auto Efficient (kilo-auto/efficient) classifies each request by difficulty and routes it to the cheapest model that Kilo’s ongoing benchmarks show is accurate enough for that task. You can restrict it to a pool of models you trust, and when it can’t make a confident call it falls back to a fixed baseline model.
Through Kilo Gateway you pay per token across 500+ models, so there’s no weekly cliff to plan around, and you can bring your own provider keys.
The same standard applies to us. Per-token billing doesn’t make Fable cheaper. Run Fable on everything in Kilo and your bill shows the same 2x and 4x math the subscription meter does. The difference is that you see it per request, as it happens, instead of finding out on Monday.
Kilo co-founder Emilie Schario made the same case in her All Day AI keynote, “Your AI Coding Bill Isn’t the Problem.” And for teams that run Kilo as part of Anaconda Platform, AI Workspaces let admins choose approved models without lock-in and route them to control spend. You can find more talks like hers under Ask the Experts in Anaconda’s Video Hub.